CineV: From Motion Research to a Production AI Creation Platform
Connecting motion research, editable 3D direction, and multimodal agents into a production workflow for stories, storyboards, and animation.
From Research to Creative Control
CineV brought AI and 3D tools into a connected animation workflow: develop a story, build a storyboard, direct a scene, and generate images and video. The central challenge was to make generated content editable and reusable across a production, while giving creators control over characters, motion, and camera composition.
At Cinamon, I worked as an AI Research Engineer and AI Lead, connecting motion research and data infrastructure with production AI systems. My contributions spanned motion-model delivery, agent architecture, and editable 3D reference workflows. I took a leading role in PoseShot and supported Shotloom through the interfaces and integration work it needed.
Explore the CineV product and technology archive · See production showcases
Watch the technical demos: Storyboard workflow · PoseShot controls · Shotloom workflow and output · Motion and retrieval · Unreal Studio. Each clip includes a short explanation of what to look for.
Three outcomes connect this work:
- Story to storyboard: story intent, reusable references, shot images, and video generation became parts of a persistent project workflow.
- Editable 3D direction: creators could revise poses, character placement, and cameras before using those decisions to guide generation.
- Motion research in production: data processing, motion generation and retrieval, and model serving provided reusable capabilities for creative tools.
Role and scope: AI Research Engineer at Cinamon from February 2023; AI Lead from October 2023. The agent-platform phase began in February 2026. This retrospective covers work across those phases; the product demonstrations below are team outcomes, with my contribution identified separately.
Selected Product Outcomes
Story to Storyboard: Agent Planning and A2P
The result. CineV’s archived workflow follows five concrete steps: story input, reference review, shot-image creation, animation planning, and video-clip generation. Characters, backgrounds, and props are managed at the project level so creators can reuse them across shots. The A2P development archive documents the broader progression from generation experiments toward a consistent, editable production workflow.
My contribution. I proposed the initial LangGraph-based proof of concept and worked with the team on the first end-to-end story-planning agent implementation. The agent inspected structured state, selected tools, and determined the next planning step. I also contributed to the semantic state, visual-reference binding, and durable orchestration that connected planning to image and video generation in the product.
The engineering goal was to carry story meaning and asset identity between stages while allowing creators to revise the result.
Inside the Production Workflow
The canvas clip shows the product interface; the finished short below shows a downstream creative result. Together they connect the workflow to what creators can produce.
Explore the storyboard workflow · Read the A2P development record
PoseShot: Directing the Image in 3D
The result. PoseShot turns an image into a starting point for editable 3D character poses and placement. Creators can adjust camera angles, refine body joints and hands, and use motion capabilities to find or generate a pose. The edited scene becomes a visual reference for downstream image and video generation.
My contribution. I took a leading role in developing the pose and reference-image workflow, connecting image-to-pose, pose search, camera composition, and downstream generation. This gave creators a way to express spatial intent through an inspectable scene rather than repeatedly rewriting a prompt.
Camera, Motion, and Pose Controls
These focused clips show the editable controls behind the broader pose-and-shot demo above.
Explore PoseShot’s results and editing tools
Shotloom: From a Shot to a Directed Sequence
The result. Shotloom opens a storyboard image as an editable 3D scene. Creators arrange characters and props, apply motion, and animate camera position, rotation, and field of view on a timeline. SceneGen then uses the directed scene to generate video. A generated video’s last frame can return to the CineV storyboard as the starting point for another shot.
My contribution. I supported Shotloom by providing required interfaces and collaborating on integration. The editor and the full Shotloom product are team outcomes; my role here was enabling the connected workflow.
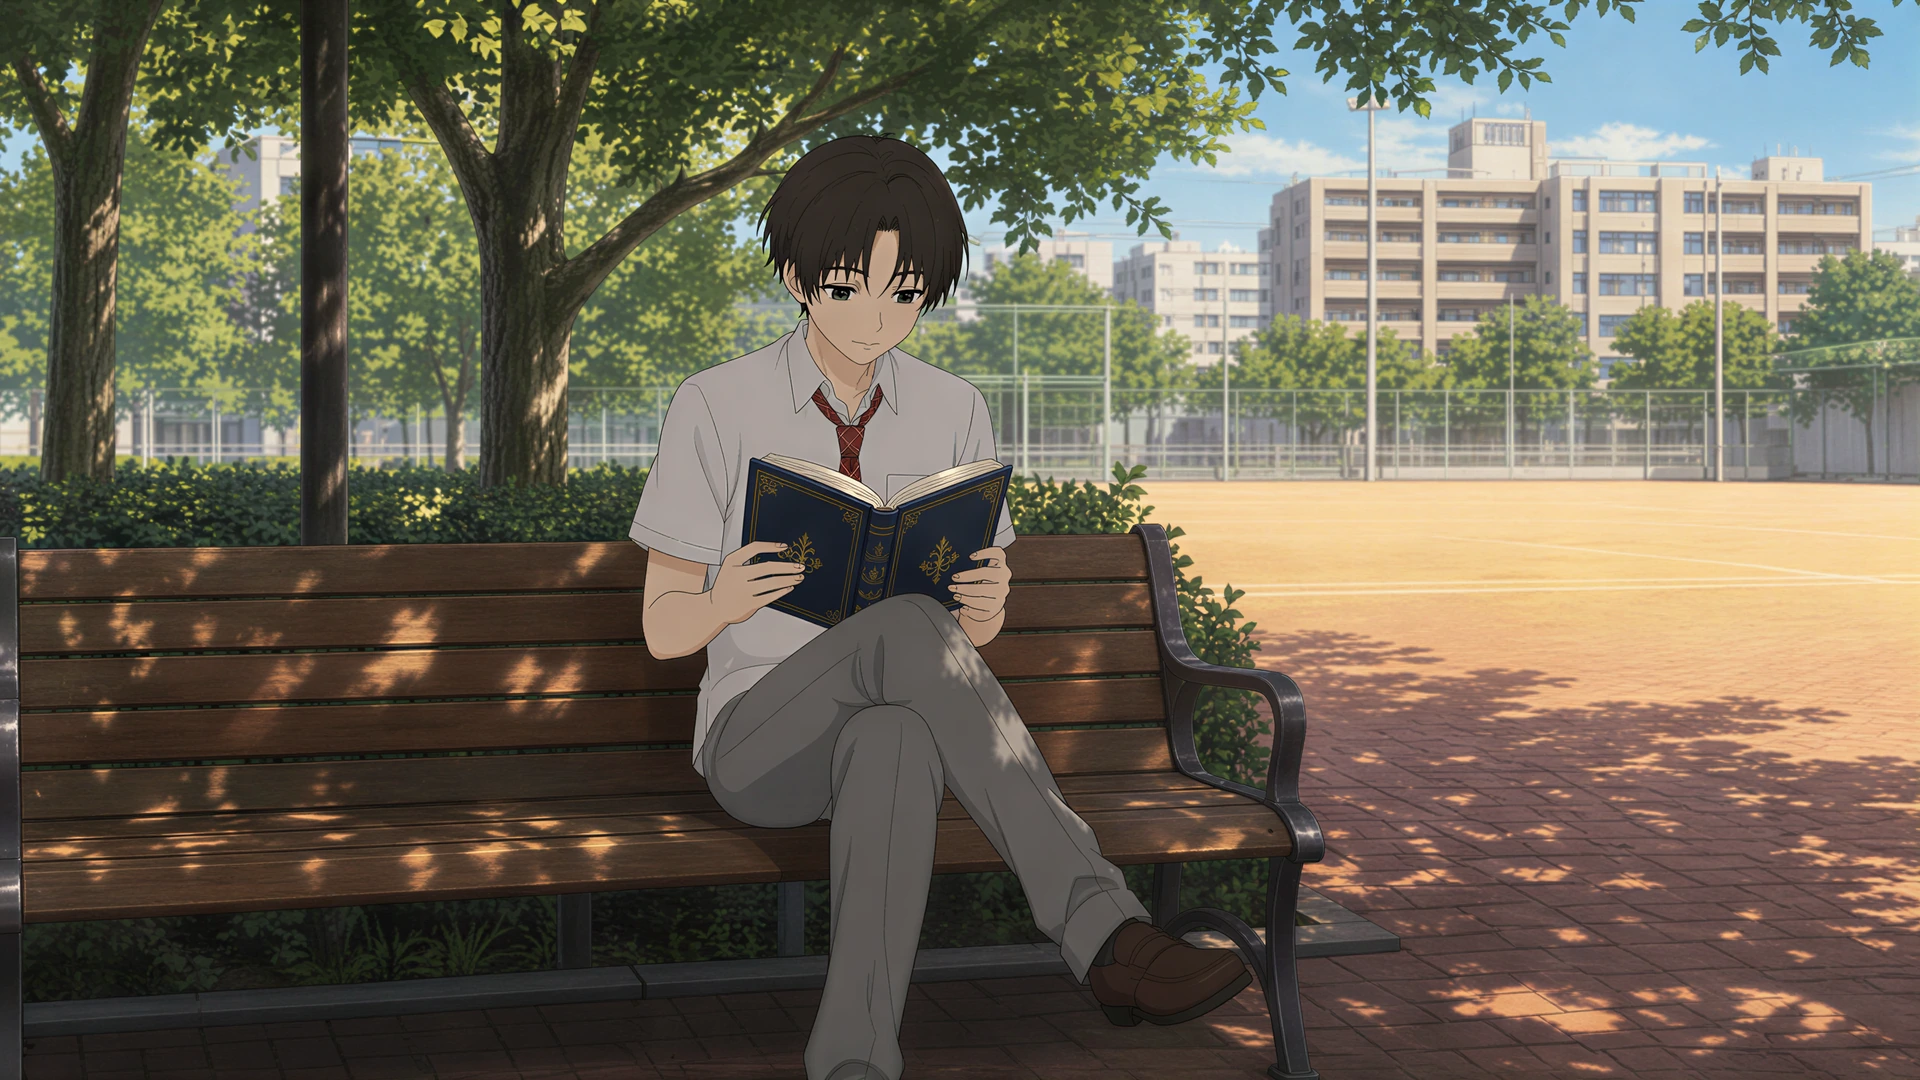
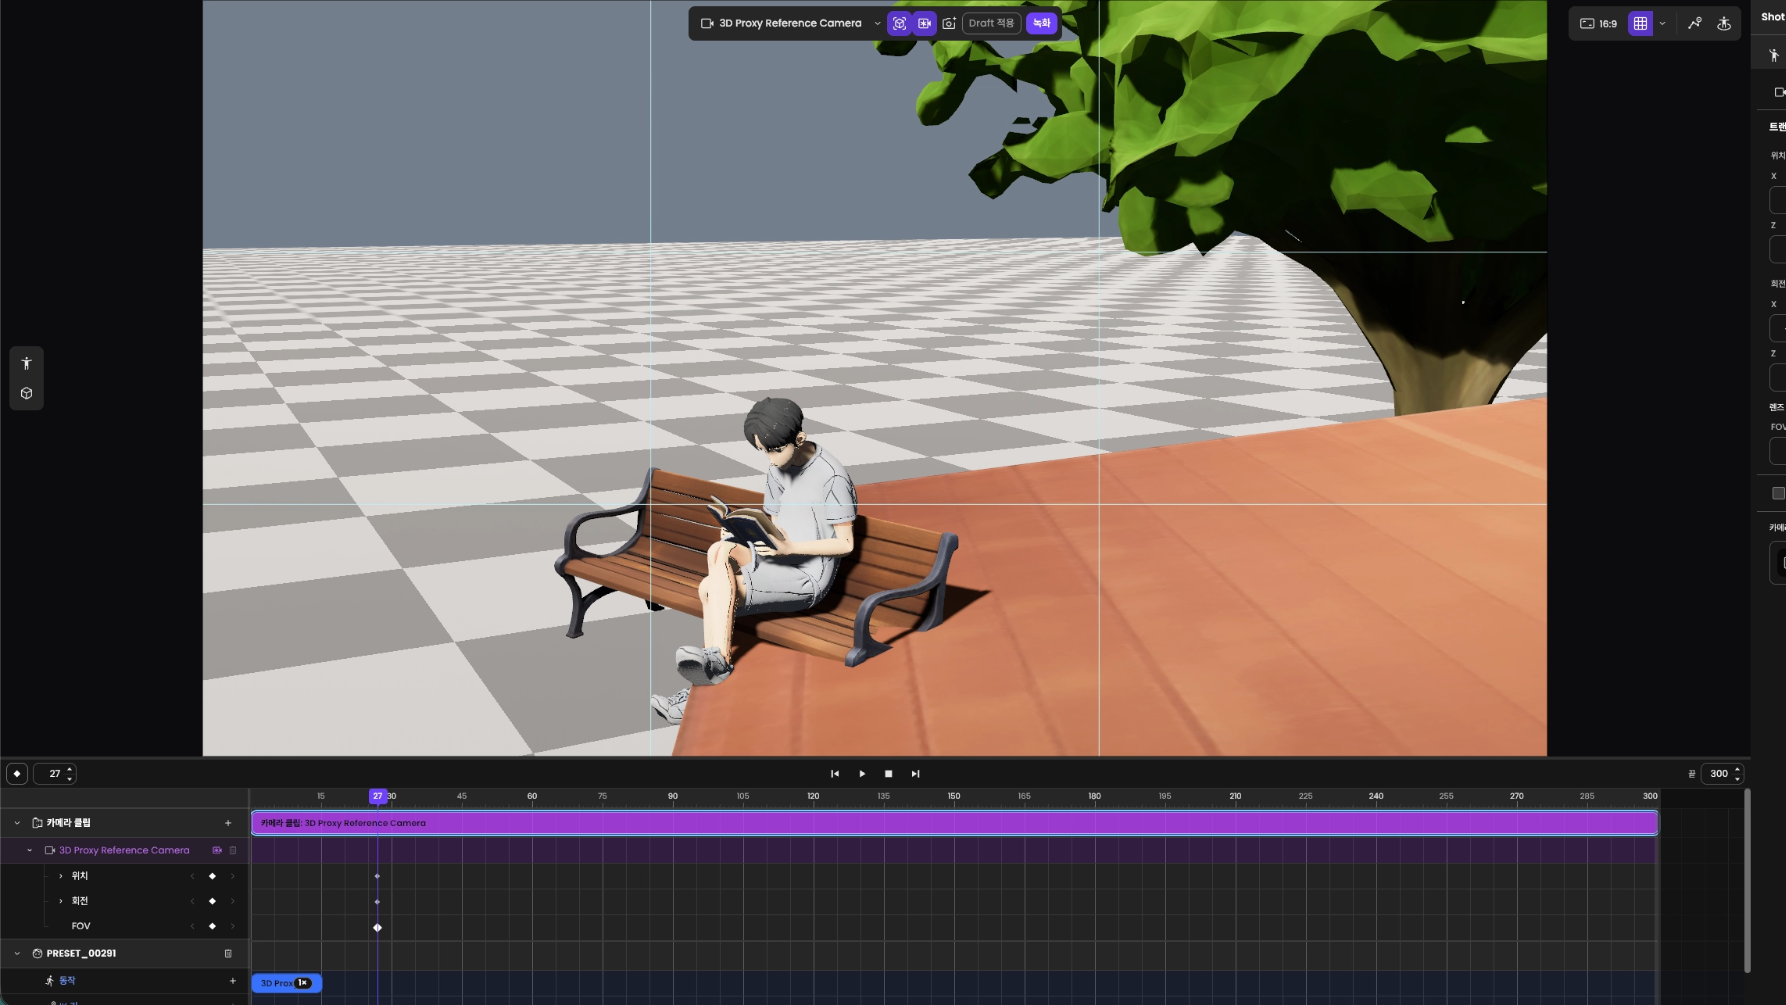
Images reproduced from the Shotloom development archive, © 2026 CINAMON, Inc. Original shot source · Edited scene source.
From Editing to the Generated Result
Explore the complete Shotloom workflow
The Foundation: Motion Research, Data, and 3D Studio
These tools grew from a broader foundation in motion and 3D production. My work at Cinamon connected data preparation and model research to capabilities that product teams could integrate and reuse.
| Foundation | My contribution | Further evidence |
|---|---|---|
| Motion data | Built the initial Motion Capture Processor architecture, connecting asset conversion, normalization, retargeting, and visual validation to training-ready data. | Motion data platform |
| Motion models and delivery | Helped set research direction across text-to-motion, retrieval, pose-to-pose, refinement, and stylization; connected research workflows to model export and serving. | Research-to-production platform |
| Controllable motion research | Contributed as corresponding author to COMET, exploring controllable long-horizon motion generation. | COMET |
| Creative-tool integration | Worked on reusable motion and asset capabilities that supported posing, staging, and downstream generation, in collaboration with the teams building the product experience. | CineV technology archive |
Motion Capabilities and Data Inspection
The clips below make the research capabilities concrete: generate an action, connect movements, change style, explore variation, account for the scene, and retrieve reusable motion. The first five reuse the demonstrations in my motion-model project; the browser clip comes from the public CineV archive.
Motion and Cameras in Unreal Studio
The earlier Unreal-based CineV Studio provided a browser-accessible 3D production environment for characters, motion, cameras, and timelines. Later workflows combined generated media with selective 3D guidance. The common thread was creative control: retaining editable decisions about how a scene is staged and filmed as the generation technology changed.
These Studio clips demonstrate the earlier product interface. The finished film below shows a team production made with that full 3D approach.
Connecting the System
The architecture needed to preserve editable intent across language, vision, 3D, and media-generation boundaries. The following diagram summarizes the later agent-and-3D workflow rather than the chronology of every CineV product.
flowchart TB
    A["Story Intent + Reusable Assets"] --> B["Agentic Planning<br/>State + Tools"]
    B --> C["Shot Intent + Visual References"]
    C --> D["Editable 3D Direction<br/>Pose + Motion + Camera"]
    U["Creator Revisions"] --> D
    M["Motion + Asset Foundation"] --> D
    D --> E["Image + Video Generation<br/>Durable Execution"]
    E --> F["Review + Storyboard"]
    F --> C
- Explicit state and references: typed story entities, shot intent, and identity-bound visual references carried meaning across model and provider boundaries.
- Editable spatial intent: pose, motion, and camera state made creative decisions inspectable before generation, with tools providing grounded project and spatial context to the agent.
- Durable execution: long-running generation required persistent results and recovery paths for provider failures, retries, and user revisions. I contributed to these orchestration paths with the Web Service and DevOps teams.
Development Friction and Lessons
The difficult part was turning independently promising capabilities into a workflow that could be tested, integrated, and operated repeatedly.
| Friction | Improvement I contributed to | Why it mattered |
|---|---|---|
| Experiments waited for full product integration. | A separate internal development deployment and a repeatable path from prototype validation to product adoption. | The AI team could inspect candidate capabilities earlier and give integration teams concrete behavior to evaluate. |
| Different models reinterpreted story and scene information. | Explicit semantic state, stable visual-reference binding, and shared API and event contracts. | Intent and identity had a defined representation at each boundary. |
| Failures crossed workflow and model boundaries. | Shared monitoring, distributed tracing, and regression evaluation. | Engineers could investigate recurring failure patterns and validate fixes with more context. |
Lessons for future systems. Treat the editable intermediate representation as a product capability. Define integration contracts early, preserve representative failure cases as regression inputs, and connect each product claim to an observable result. These are design lessons from the work, not claims of measured performance gains.
Technology used across these contributions: Python, PyTorch, Ray, Blender, ONNX/Triton; LangChain, LangGraph, Pydantic, FastAPI, Inngest, MongoDB; LangSmith, OpenTelemetry, Datadog, and pytest. Deployment and operations involved Docker, Kubernetes, Helm, and ArgoCD in collaboration with DevOps.
Explore the Work
The public archive preserves the product experience, development records, and creative results. This page selects the outcomes most relevant to my work; the archive provides the broader team context.
CineV product and technology archive · Production showcases · PoseShot · Shotloom · A2P